 Ficelle
What is an LLM gateway? Routing, reliability, and cost control
An LLM gateway sits between your code and model providers. Here is a practical map of its five layers (compatibility, routing, health, cost policy, maintenance) and which ones Ficelle actually owns.
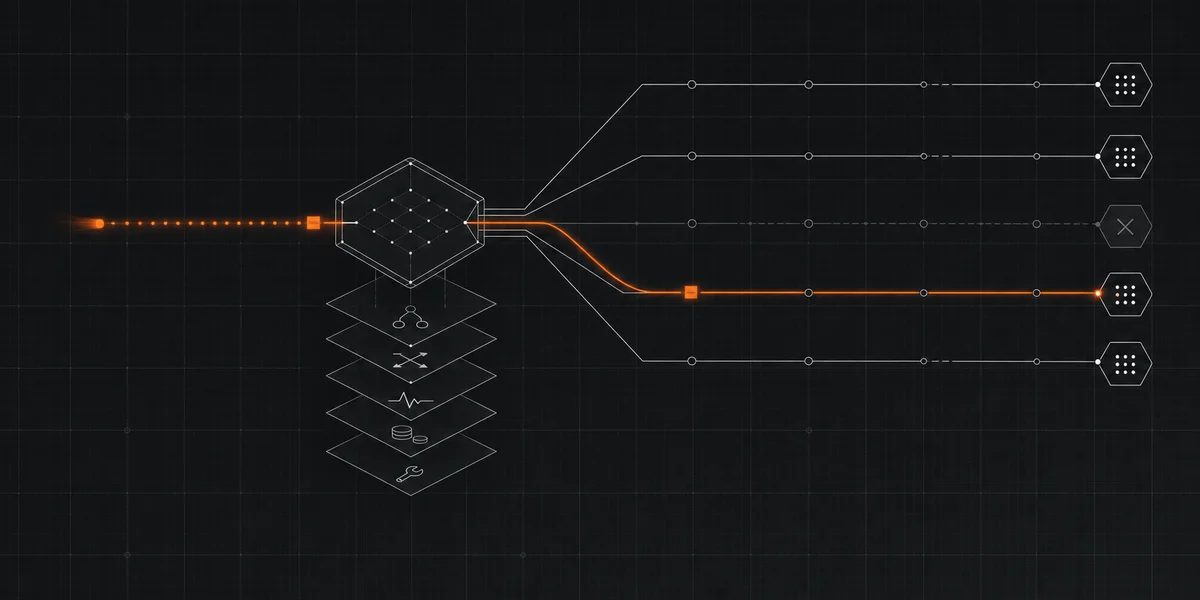
An LLM gateway is the layer between your application and the model providers it calls. Your code talks to one endpoint; the gateway decides which provider and model actually serve the request, what happens when that provider fails, and what the request is allowed to cost. The term “AI gateway” is used for the same idea, usually with more emphasis on enterprise governance.
The category is easier to evaluate once you split it into layers, because no two gateways own the same ones. A team buying governance for hundreds of internal users needs something different from a solo developer whose coding agent keeps hitting free-tier quotas.
How the category defines itself
Kong’s documentation gives a representative definition. Its AI Gateway is described as a “connectivity and governance layer for modern AI-native applications”, and the capabilities it lists map the territory well:
- connecting to major LLM providers “through one consistent API”, so you can “switch or combine providers without rewriting your integration”;
- routing and load balancing across AI providers;
- automatic failover “to a different provider or model when one is slow or unavailable”;
- token budgets by team or department;
- semantic caching that serves repeated or near-duplicate prompts without calling the upstream model again;
- prompt guards that block disallowed topics and redact PII before it reaches the provider;
- usage analytics for requests, tokens, errors, and latency, plus model cost management.
That is a broad feature set, and for an organization that needs central policy over many applications and teams, it is the right shape. A multi-provider LLM gateway at that scale is a platform decision, owned by a platform team.
The five layers of an LLM gateway
Stripped of vendor packaging, most gateways combine five distinct jobs.
1. Compatibility. One API surface in front of many providers. In practice this usually means the OpenAI chat-completions format, because most SDKs, agent frameworks, and coding tools already speak it. Compatibility is the cheapest layer to build and the first one people mistake for the whole product.
2. Routing. Choosing a provider and model for each request: by capability, by priority, by load, or by price. A routing rule is only as good as the information it routes on.
3. Health. Knowing which routes work right now. Providers rate-limit, retire model IDs, and advertise capabilities their models do not reliably deliver. A gateway that routes on catalog claims alone sends traffic to dead or degraded endpoints. This is the layer that separates a router from a reliability system, and the one covered in depth in why provider breakage is the silent killer of AI agents.
4. Cost policy. What a request is allowed to spend. In enterprise gateways this usually means budgets and quotas per team. For a cost-sensitive agent the more important question is narrower: when the cheap route fails, does the gateway quietly retry on a paid one?
5. Maintenance. Someone has to keep the provider integrations, model lists, and quirks current. Provider catalogs change continuously, so a gateway you configured once and never update decays into a list of broken routes. This layer is rarely on feature pages, but it is where most of the ongoing operational cost lives.
Which layers matter for cost-sensitive agents
If you run coding agents or prototypes on free and free-tier models, the layers carry different weight than they do for an enterprise.
Compatibility is table stakes: your agent already speaks the OpenAI format and should not need rewriting. Health matters more than usual, because free LLM APIs are the most volatile endpoints in the ecosystem, with quotas that differ by model and tighten without notice. Cost policy becomes a hard safety requirement rather than a reporting feature, since a single silent paid fallback inside an agent loop that fans out into thousands of calls defeats the reason you chose free models. And maintenance is the hidden bill: every hand-built setup eventually turns into a weekly chore of updating model IDs and provider configs.
Governance features such as team budgets, PII redaction, and central analytics across departments matter less here. Choose them according to the governance your application needs.
Which layers Ficelle owns
Ficelle is a local, OpenAI-compatible router focused on free models. Mapped onto the five layers:
- Compatibility. Ficelle exposes a local OpenAI-compatible endpoint (
http://127.0.0.1:8646/v1). Tools that accept an OpenAI base URL point at it without code changes. - Routing. Requests are routed across a pool of free models, with fallback among configured, enabled candidates that meet the request requirements. An exhausted pool returns an error.
- Health. Models that error or rate-limit go on a timed cooldown; persistent failures, such as a retired model returning 404 or 410, are quarantined out of the pool. Tool-call, JSON, and vision compliance are measured rather than trusted from provider catalogs.
- Cost policy. Strict-zero routing uses zero-price evidence on the default catalog path and explicit eligibility guards for optional quota providers. Agent profiles require tool support. It keeps paid fallback disabled:
allow_paid_fallbackis hardcodedfalse, and when every free candidate is exhausted the request returns an error. Quota-provider accounts can still bill beyond their allocation when their upstream settings permit it. An anti-false-free guard quarantines any model the runtime reports as billed. - Maintenance. The routing core is free and source-available under the Business Source License 1.1. Ficelle Pro is the maintenance layer: the full curated provider pool, fixes shipped when a provider breaks, one-command updates for the maintained provider pack, native prompt compression, custom virtual models, and priority support.
Ficelle runs on your machine, keeps provider keys local, and sends requests directly to the selected provider.
Check the provider behind the gateway
OpenRouter, Requesty, and Routeway are themselves gateways. Their free model lists come with their own account quotas and upstream data terms. Putting a local router in front of them preserves those constraints. Routeway also has unresolved conflicting per-minute limits in its official docs.
Cloudflare Workers AI adds an account-specific API URL and a compute allowance measured in Neurons. Mistral combines included monthly usage with organization/model limits. When evaluating a gateway, check whether it distinguishes these access mechanisms, shows quota exhaustion clearly, and requires confirmed account entitlement before routing.
When you need enterprise governance
Ficelle’s published feature set does not include team-level token budgets, PII redaction, topic guards, or semantic caching. If you need central governance across an organization, an enterprise AI gateway such as Kong’s is built for that job, with the policy controls that workload requires.
Strict-zero also has a cost of its own: free models are not equal to paid ones for every task. In Ficelle’s own 76-task benchmark, free routing reached quality parity with gpt-5 on classification, JSON extraction, and reasoning, but the paid model won 50% of the polished long-form writing tasks. Customer-facing writing is still a workload to keep on a paid model or to edit by hand.
Choosing an LLM gateway
Start with the layer that hurts. If your problem is governance across teams, evaluate enterprise gateways on policy, analytics, and security controls. If your problem is that an agent built on free models keeps breaking, or that you are afraid it will spend behind your back, the layers to evaluate are health, cost policy, and who does the maintenance.
That last question is the one Ficelle sells an answer to. The router is free to run; if you would rather not maintain the provider pool yourself, see Ficelle Pro pricing.
